Linear Regression
linear_model.LinearRegressionPredicts a continuous number by fitting the straight line that best relates the input variables to the output.
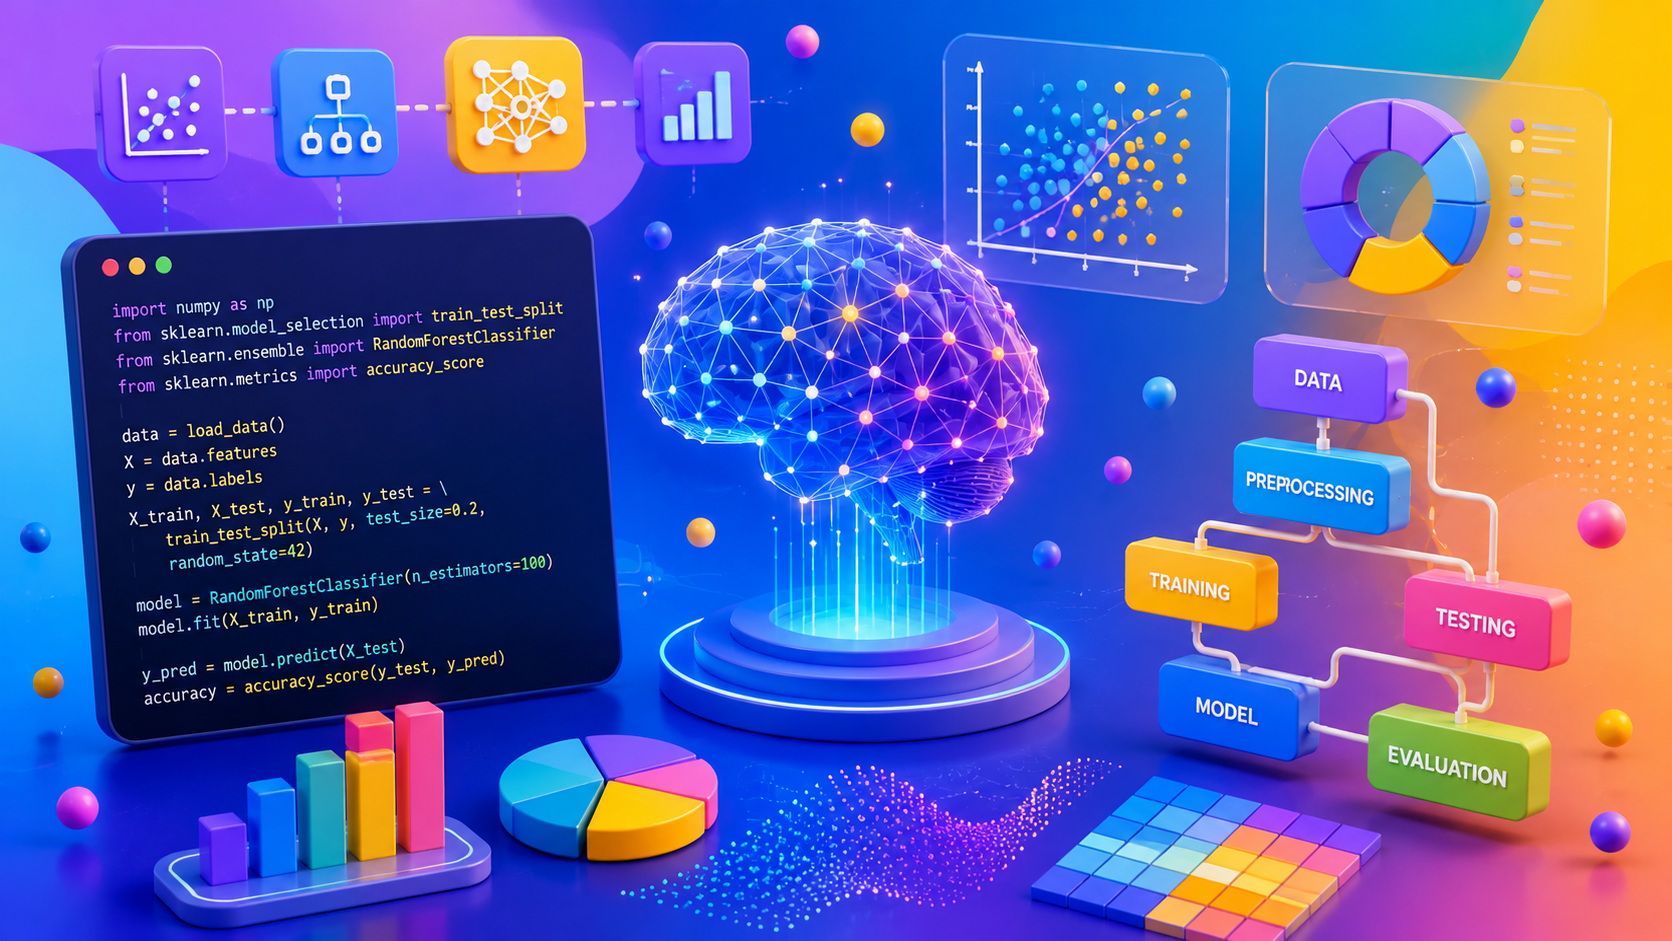
This course provides a practical introduction to the fundamental principles, algorithms, and real-world applications of Machine Learning (ML). Designed for aspiring data scientists, AI developers, and software engineers, this program bridges theoretical mathematical foundations with modern hands-on implementation.
Students will cover the entire machine learning pipeline—from exploratory data analysis and feature engineering to model training, hyperparameter tuning, evaluation, and deployment. By the end of this course, learners will be capable of identifying appropriate ML algorithms for complex real-world problems and building end-to-end predictive systems.
This course is backed by trusted partner organizations, highlighting strong industry alignment, recognized quality, and professional credibility.
PEZA
Certified Track
DOST
Certified Track
University of Perpetual Help
Certified Track
...and the two ideas nested inside it that make modern AI work: machine learning, and deep learning.
This course works through thirteen classical models, grouped the way they're taught: first by how the model learns, then by the task it solves. Each one is paired with the scikit-learn estimator you'll use in the labs.
The model trains on labelled examples — inputs paired with known, correct answers — and learns to predict the answer for new, unseen inputs. Three tasks live here: predicting numbers, predicting categories, and combining many models into one.
Predicting a continuous, numeric value
Predicts a continuous number by fitting the straight line that best relates the input variables to the output.
Improves plain linear regression by penalising large coefficients, which prevents overfitting and can drop weaker features entirely.
Sorting data points into labelled categories
Predicts the probability of a categorical outcome, like yes or no, using an S-shaped curve instead of a straight line.
Splits data into branches based on feature values, ending in leaves that each represent a final predicted class.
Classifies a new point by taking a majority vote among its closest neighbours already present in the data.
Estimates the probability of each class using Bayes' theorem, assuming the input features are independent of one another.
Finds the boundary that separates two classes by the widest possible margin between their closest points.
Combining many simple models into one strong one
Trains many decision trees on random subsets of data and averages their votes for a more accurate, stable prediction.
Builds an ensemble of weak models one at a time, where each new model corrects the errors left by the ones before it.
Trains a sequence of simple classifiers, giving more weight each round to the examples the previous ones got wrong.
These models never see a labelled answer. They explore the raw structure of the data itself — grouping similar points together, or compressing many features down to the few that carry the most information.
Grouping unlabelled points by similarity
Groups unlabelled data into a set number of clusters by repeatedly assigning each point to its nearest cluster centre.
Builds a tree of nested clusters by progressively merging the most similar groups of data points together.
Compressing many features into the few that matter
Reduces the number of features in a dataset while preserving as much of its original variance as possible.
Start from the question you're trying to answer, then read across.
| If your question is… | Task | Start with | Labels needed |
|---|---|---|---|
| “How much?” or “How many?” | Regression | LinearRegression, Ridge |
Yes |
| “Which category does this belong to?” | Classification | LogisticRegression, SVC |
Yes |
| “Can I squeeze out more accuracy?” | Ensemble | RandomForestClassifier |
Yes |
| “What natural groups exist here?” | Clustering | KMeans |
No |
| “Too many columns to work with.” | Dim. reduction | PCA |
No |
This course provides a practical introduction to the fundamental principles, algorithms, and real-world applications of Machine Learning (ML). Designed for aspiring data scientists, AI developers, and software engineers, this program bridges theoretical mathematical foundations with modern hands-on implementation.
Students will cover the entire machine learning pipeline—from exploratory data analysis and feature engineering to model training, hyperparameter tuning, evaluation, and deployment. By the end of this course, learners will be capable of identifying appropriate ML algorithms for complex real-world problems and building end-to-end predictive systems.
Choose any lesson to open the immersive learning interface.
 NEXI
NexusPro guide